Demonstrations and trajectories for robots that work with their hands.
Data for perception, manipulation, and policy learning, scoped around your tasks, environments, and embodiment. We define capture setups, action labels, and synchronization requirements with your team before collection begins.
Who it is for
Teams we work with
- Robot learning and policy teams
- Humanoid and mobile manipulation companies
- Industrial automation and picking teams
- Perception teams working on hands and objects
Objective
Teach and evaluate policies that perceive objects, plan contact, and complete multi-step tasks reliably across environments.
Data categories
What Robotics Data covers
Egocentric human demonstrations
First-person task recordings from head-mounted cameras.
Wrist-camera & multi-view capture
Close-range and synchronized external views of the same episode.
Teleoperated & UMI-based demonstrations
Demonstrations collected through teleoperation or handheld grippers, scoped per project.
Robot state & action trajectories
Joint states, end-effector poses, and commanded actions over time.
Tactile & force signals
Contact and force measurements aligned to video, where the setup provides them.
Know what you are getting
Human demonstrations, robot trajectories, and sensor measurements are different data.
We keep them distinct in the schema and the documentation, so nobody mistakes a label for a measurement.
Human demonstrations
Video of people doing the task, with hand, object, and action labels added after capture.
Labels are annotations, not robot commands.
Robot trajectories
Logged robot state and commanded actions from teleoperation or autonomous runs.
Requires access to a robot setup scoped per project.
Sensor measurements
Depth, IMU, tactile, or force readings recorded by instrumented hardware.
Present only when the capture rig includes the sensor.
Illustrative samples
Example records
HX-MAN-0612 Illustrative
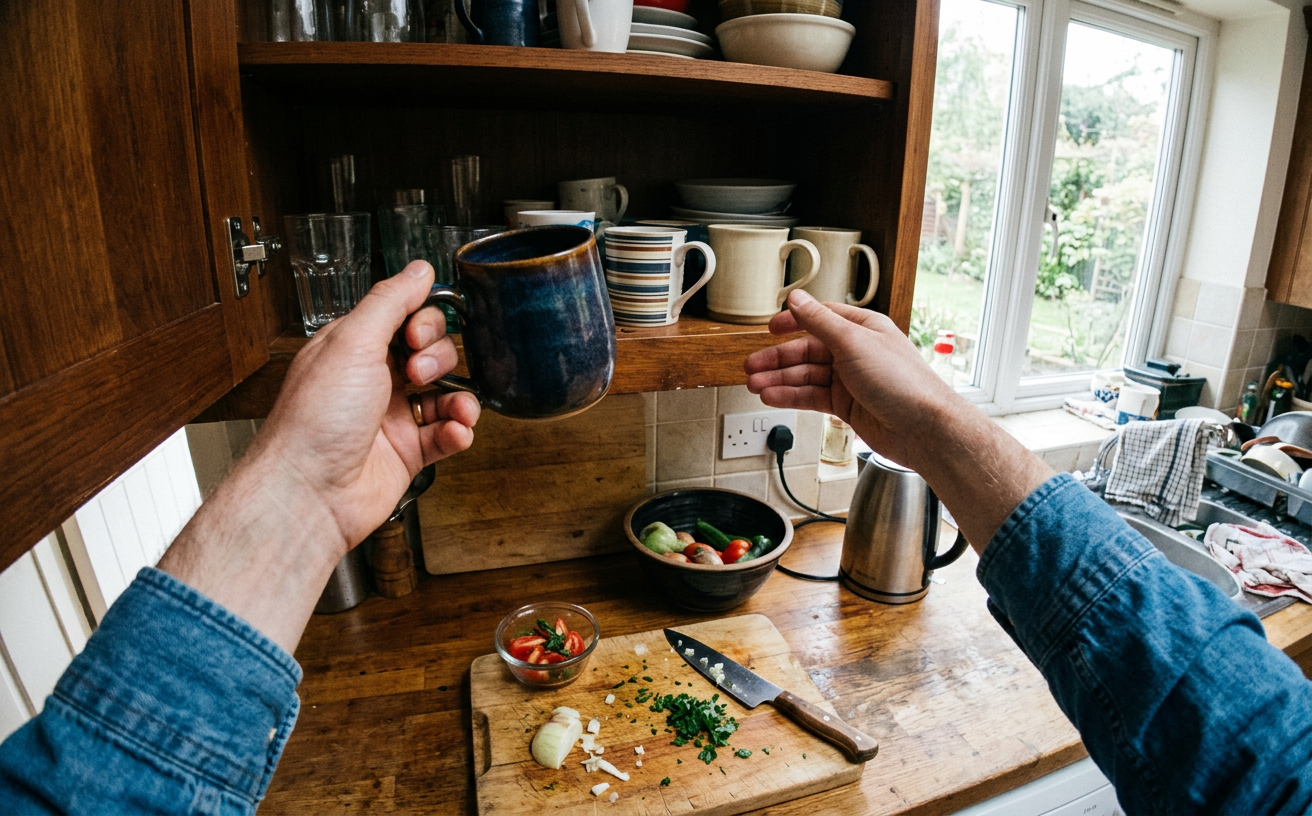
Illustrative still frame with example labels. A still image contains no trajectory or sensor data.
Kitchen mug placement
Egocentric pick-and-place in a cluttered kitchen, with hand, object, and action labels.
- Pillar
- Robotics Data
- Modality
- Video
- Use case
- Robotics & embodied interaction
- Method
- Captured + annotated
- Bounding boxes
- Action segments
- Grasp events
- Success label
Specification
What we agree before production
- Task & environment
- What is done, where, with which objects, and the variation required.
- Capture setup
- Head-mounted, wrist, fixed external, teleoperation, or handheld gripper.
- Camera views
- Number of views, placement, resolution, and frame rate.
- Episode boundaries
- Where each episode starts and ends, and how resets are handled.
- Action labels
- Action vocabulary and segment rules, such as reach, grasp, transport, and place.
- State / action schema
- Joint and end-effector fields, units, and coordinate frames, when trajectories are logged.
- Synchronization
- How streams are time-aligned, with the tolerance agreed up front.
- Success & failure
- Per-episode outcome labels and failure reasons.
Quality & governance
- Capture protocol and coverage plan signed off before recording
- Per-episode checks for boundaries, sync, and dropped frames
- Second-pass review of action segments on sampled episodes
- Participant consent and de-identification as agreed
Example deliverable
- robotics-delivery/
- episodes/
- ep_000001/
- cam_head.mp4
- cam_wrist.mp4// if captured
- actions.json// segments + labels
- state_action.parquet// if logged
- outcome.json
- calibration/
- cameras.json
- schema.json
- capture_protocol.pdf
- DATA_CARD.md
Have a specific dataset in mind?
Share the task, scale, and timeline. We will reply with questions and a proposed scope.