Data that shows how scenes change over time.
Continuous video, aligned language, spatial structure, and interaction outcomes for models that predict what happens next. We describe what is observed accurately and are explicit about what a recording can and cannot tell you.
Who it is for
Teams we work with
- World-model and video-generation researchers
- Embodied AI teams that need scene understanding
- Spatial computing and 3D perception teams
- Simulation and evaluation groups
Objective
Learn and evaluate representations of temporal dynamics, spatial structure, and the observable outcomes of interactions.
Data categories
What World Model Data covers
Continuous video sequences
Long, uncut recordings where state persists between moments.
Video–language alignment
Time-stamped captions and narration tied to specific spans.
Aligned audiovisual & sensor data
Audio and other streams synchronized to the video timeline.
Depth & spatial scene data
Depth, layout, and object relations from capture that supports them.
Object motion & state changes
Labels for when and how objects move, open, fill, or change.
Action-conditioned sequences
Sequences paired with the actions taken, where actions are recorded.
Know what you are getting
What a recording shows, and what it does not.
Annotations describe observable changes. Depth, actions, and causes are included only when they are measured or explicitly labeled.
Observed
What is visible or audible: objects, positions, contacts, state changes.
Annotated directly from the recording.
Measured
Depth, pose, or sensor values from instruments in the capture setup.
Absent from plain RGB video.
Recorded actions
The actions taken, logged at capture time or labeled by annotators.
Video alone does not establish causality.
Illustrative samples
Example records
HX-SEQ-0310 Illustrative
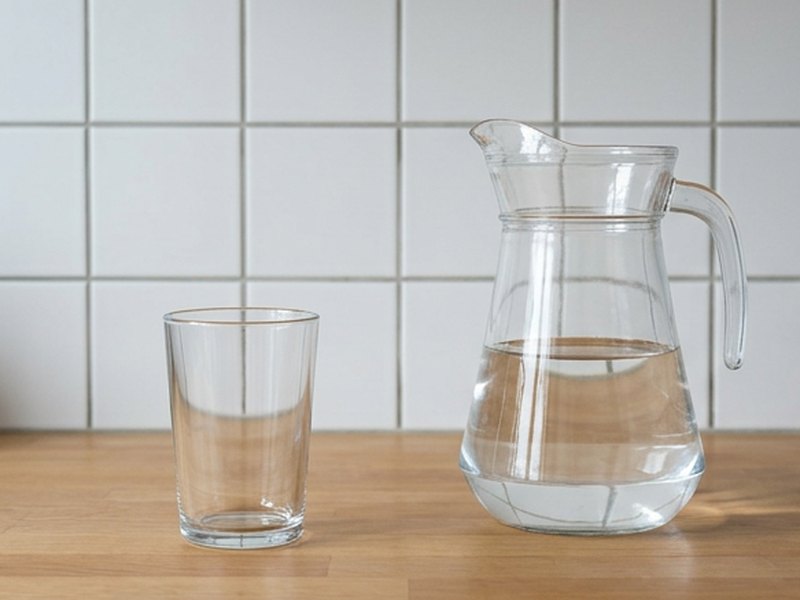 t = 00:00.0 · frame 1/4
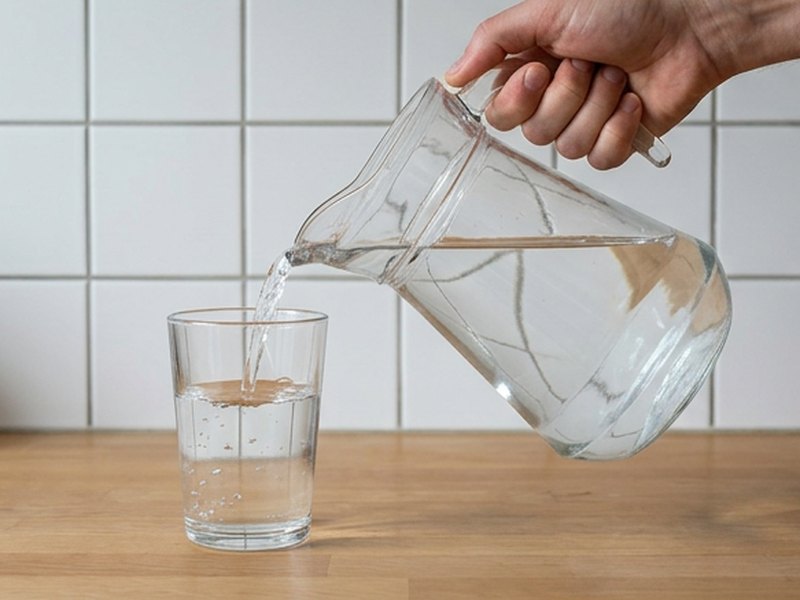
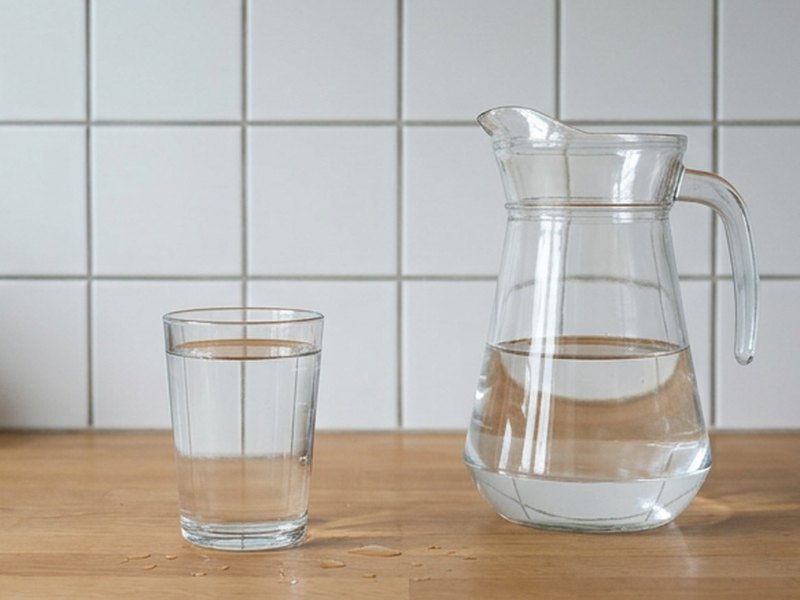
initial_state
Empty glass beside a full pitcher on the counter.
- glass.fill = empty
- pitcher.fill = full
- pitcher.pose = upright
- Contact
- none
- Hand visible
- no
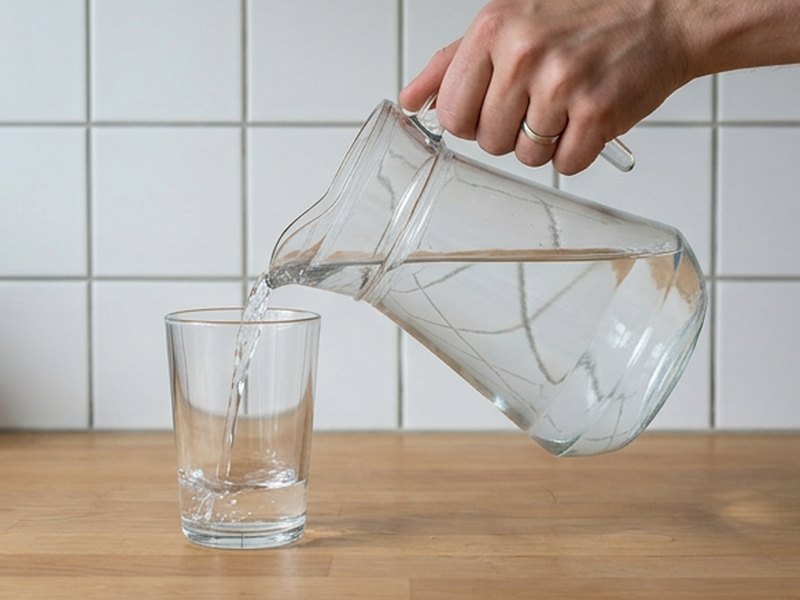
Clearly labeled storyboard illustrations, not frames from recorded footage.
Pouring: liquid level change
Four-frame storyboard with state-change events, object states, and timing per frame.
- Pillar
- World Model Data
- Modality
- Video
- Use case
- World models & temporal prediction
- Method
- Human-annotated
- Object states
- State-change events
- Contact
- Frame timing
Specification
What we agree before production
- Sequence length
- Clip duration and whether recording is continuous or segmented.
- Frame rate & resolution
- Stated per dataset, and constant within an episode.
- Event annotations
- Time-stamped start and end of state changes and interactions.
- Language alignment
- Caption granularity, timing tolerance, and vocabulary rules.
- Spatial data
- Depth or 3D layout, only if the capture setup measures it.
- Action conditioning
- Action fields and source: logged, teleoperated, or annotated.
Quality & governance
- Event boundary agreement checks between annotators
- Caption timing verified against the video timeline
- Explicit fields for unknown or unobservable values
- Continuity checks for dropped or duplicated frames
Example deliverable
- world-model-delivery/
- sequences/
- seq_000001.mp4
- seq_000001.events.json// state changes
- seq_000001.captions.json// time-aligned
- spatial/// if captured
- seq_000001.depth/
- schema.json
- DATA_CARD.md
Have a specific dataset in mind?
Share the task, scale, and timeline. We will reply with questions and a proposed scope.